Dismissing four notices in a row on an internal board took the page down with a 502 Bad Gateway, the error you get when the server stops answering. We went through the day's batch, dropped the first three, and on the fourth we sat there looking at the error until the process came back on its own. Three clicks of work and one of contemplation.
The 502 arrived on the fourth click
The board gathers notices that show up every day in public sources, and somebody moves them between states: pending, in progress, closed or dismissed. In each batch, most have nothing to do with cameras or photography, so dismissing is the most frequent operation in the system and it was the one killing it.
The first suspect was the network, because a 502 usually smells like a proxy. But this 502 showed up on the third or fourth click every time, and the process manager log showed a restart for memory on each one.
A notebook that got rewritten whole
Everything lived in a single 130 MB JSON file holding tens of thousands of notices. Changing a card's status read the 130 MB into memory, turned that text into objects, changed one field in one record, turned everything back into text, and wrote the whole file again. All of it ran synchronous, so the file rewrite alone kept Node blocked between 3 and 5 seconds, serving nothing else. It was like copying out the repair desk's logbook by hand every time you cross out a line, when what we needed was the card file: you pull one card, fix it, put it back.
Memory peaked at around 800 MB per write, because for an instant the text we read, the objects in memory, and the new text all sit there together. That peak went over the process manager's ceiling, the service restarted, and that produced the 502 on screen.
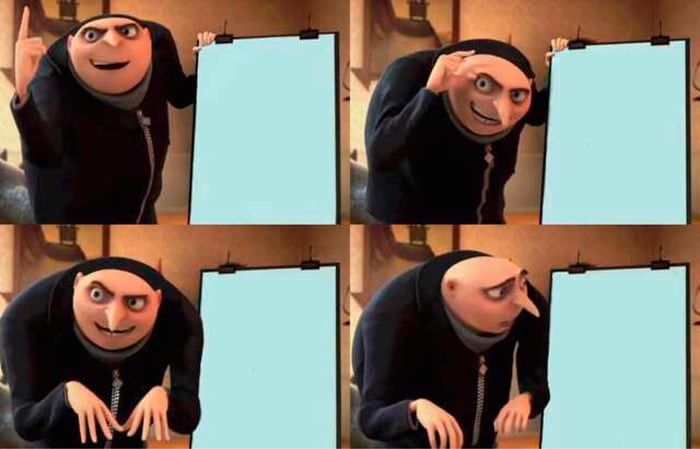 All in one JSON
Dismiss with a click
Rewrite it all per click
Rewrite it all per click
No optimization inside the JSON helped
We could parse the text faster, write it in chunks, or push the write to a separate thread. None of those three changes the storage model: to change one line you had to rewrite all the others, and the file grows every day with the new notices. Keeping everything in one text file was my idea and it held up for months, which is the most expensive way to be wrong.
Columns to filter by, one data column for the rest
We moved the tables the board touches all day to SQLite in WAL mode (write-ahead log, which lets one process read while another writes). The schema is hybrid on purpose, with a few indexed columns for what the board filters and sorts by, and the full object stored as JSON in a data column. Each notice became its own card, and adding a new field still costs close to nothing.
The process that brings in new data and the one that serves the board open the same file, each with its own connection. For concurrency we rely on WAL plus a busy timeout of 5 seconds: if the file is busy, the other process waits instead of failing. We didn't add a lock in the application because at this write volume there's no need for one.
The small config files stay as flat JSON. They get written rarely, and it helps to open them by hand. We migrated nothing that didn't have a measured problem.
Bulk inserts and updates now go in a single transaction, and the batch went from about 10 s to close to 1 s. A reprocessing job that re-scores every notice against the filter rules held the CPU for 30 seconds, so it came out of startup: it runs only when those rules change, not every time the service boots.
0.6 ms and ten deletes in 11 ms
A full status change, measured from click to response, went from between 4,000 and 6,000 ms to 0.6 ms. Ten deletes in a row, which used to take the process down, take 11 ms in total. Nobody told me the page was dead again.
Two processes writing the same file works at this volume. If a third process ever writes often, the busy timeout will show up in the logs and we'll have to rethink how the writing is split.
Moving tens of thousands of notices in production is frightening, so now I write the migration script, the dated backup and the rollback plan before I touch storage, and when something is slow I ask first whether it's stored the wrong way. The fourth click today is as boring as the first three.